ML / Done
Intelligent Document Assistant (RAG)
Overview
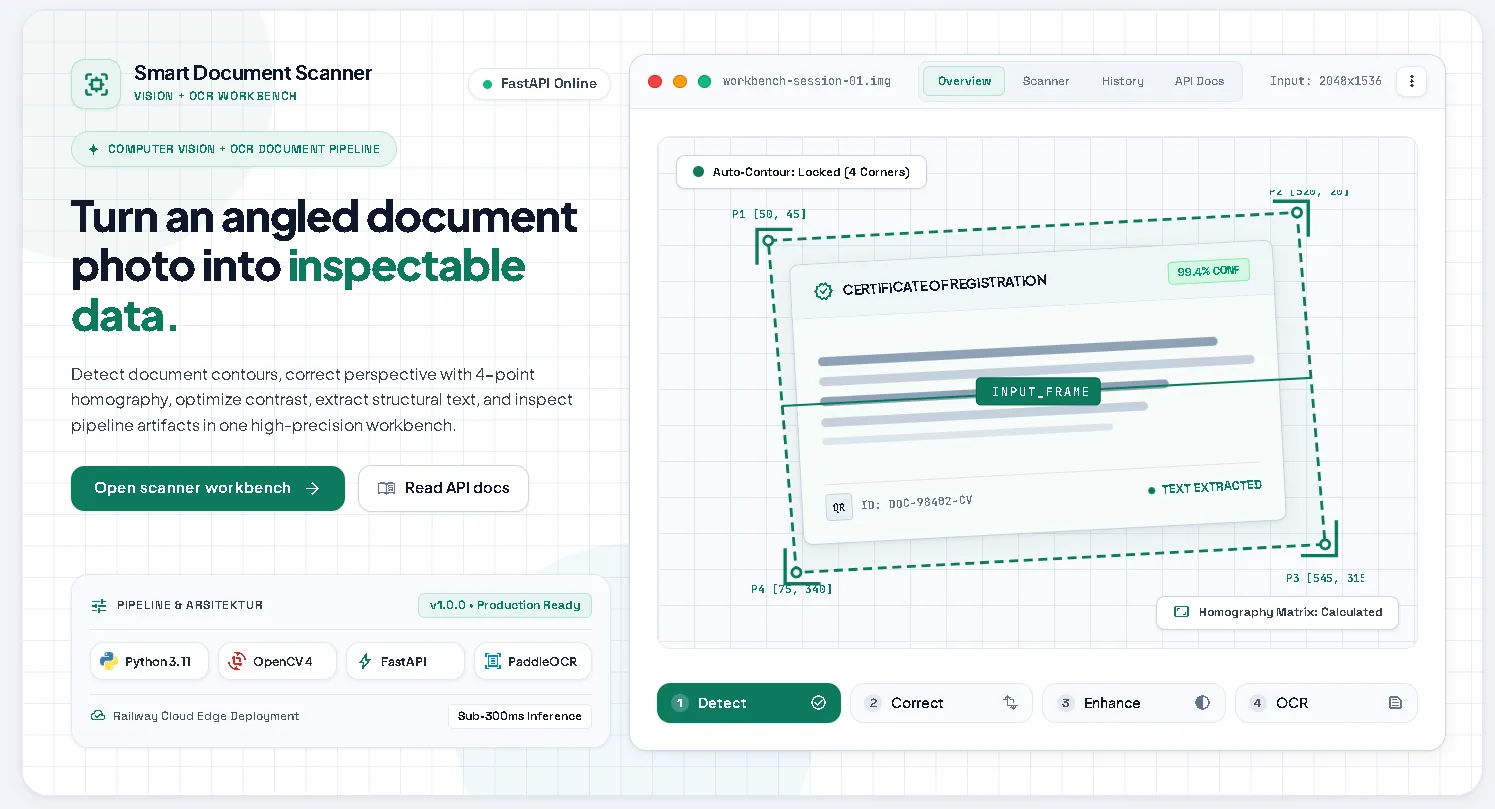
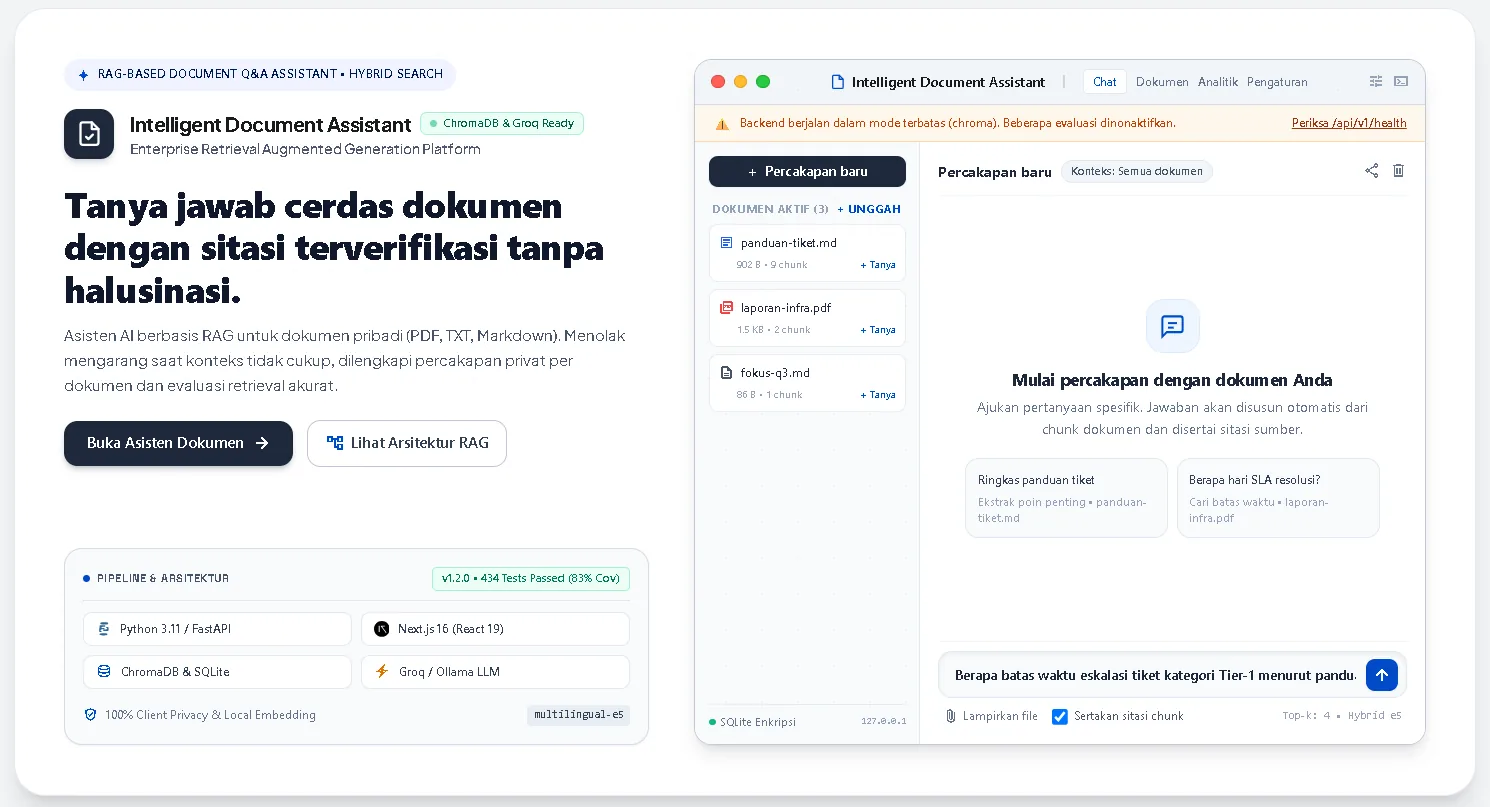
RAG-based document Q&A assistant: upload PDF, TXT, or Markdown, then ask questions in Indonesian and get answers with clickable citations. The system refuses to answer when the context is not enough, and general-knowledge answers are clearly labelled so they are never confused with document-sourced ones. Includes per-document private conversations, retrieval quality evaluation, and observability.
Challenge
Keeping the assistant trustworthy: no citation without context, a measured similarity threshold (0.82) instead of a default one because irrelevant text still scores 0.72-0.81, document scope stored in the session so private chats stay private, and a multilingual embedding model because English-only models perform far worse for Indonesian.
Result
Delivered a full-stack RAG system with FastAPI, ChromaDB, and SQLite behind a Next.js 16 frontend: 534 backend tests at 83% coverage, 59 Playwright scenarios, 21 end-to-end checks, and a RAGAS evaluation dataset where questions that must be refused are scored as strictly as the ones that must be answered.
Key Statistics
534 tests, 83% coverage
Backend tests
59 Playwright specs
Browser scenarios
multilingual-e5-small
Embedding model
0.82, measured not guessed
Similarity threshold
Technologies
Backend
-
 FastAPI
-
 Python
-
 SQLite
RAG
-
 ChromaDB
- multilingual-e5-small
- Hybrid retrieval
LLM
-
 Groq
-
 Ollama fallback
Frontend
-
 Next.js
-
 React
-
 TypeScript
-
 Tailwind CSS
Quality
- pytest
- Playwright
- RAGAS
Deployment
-
 Docker
- Caddy
- AWS EC2
Gallery
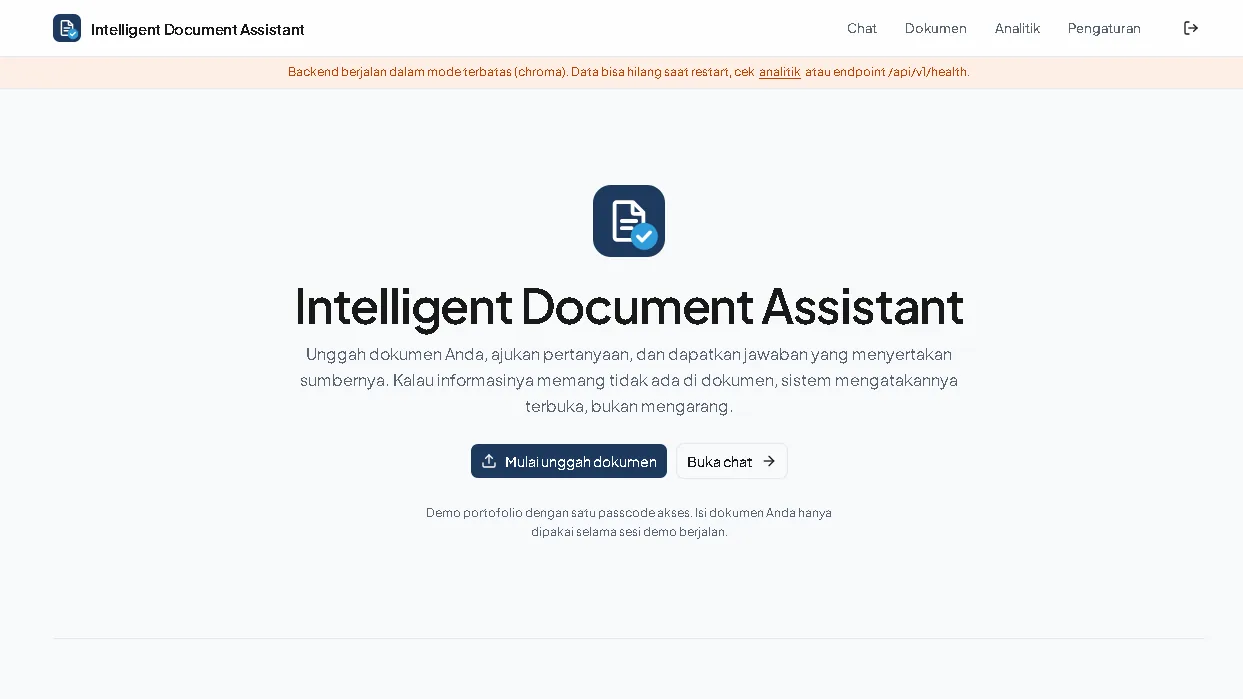
Dashboard
System overview with live document, chunk, and provider counts read straight from the backend.
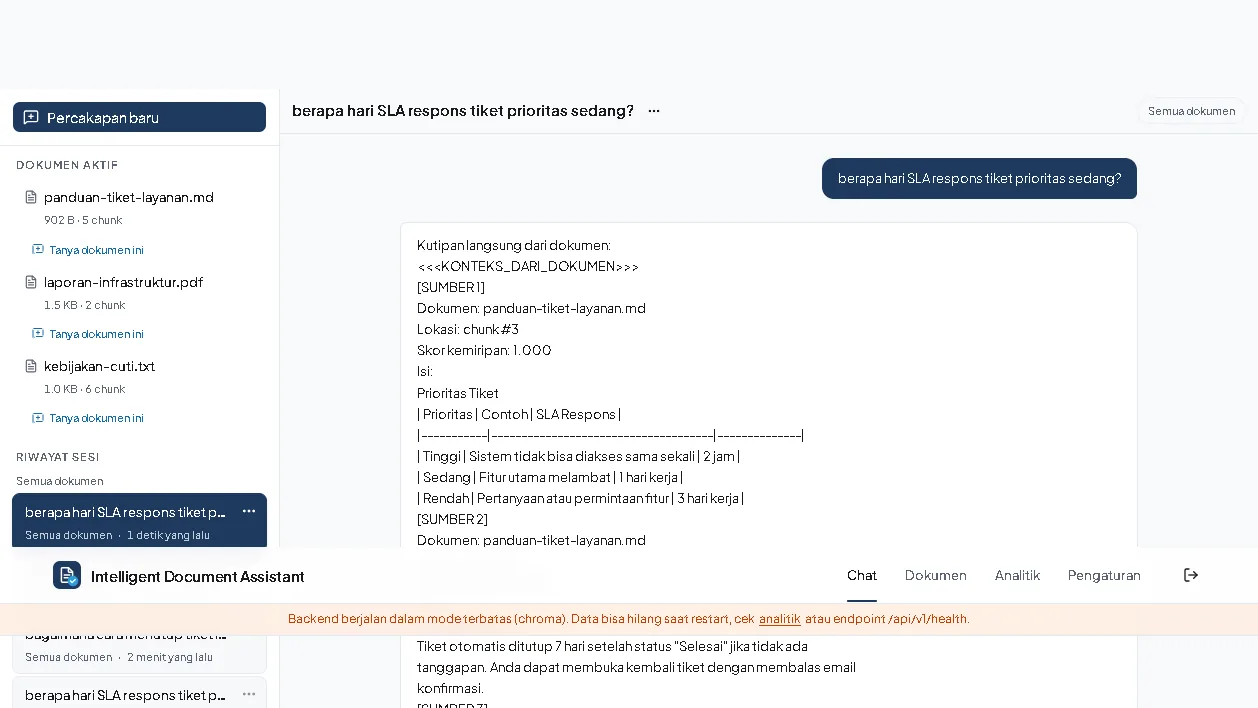
Chat with Citations
Answers stream in with a source panel that shows the quoted text, chunk number, and similarity score.
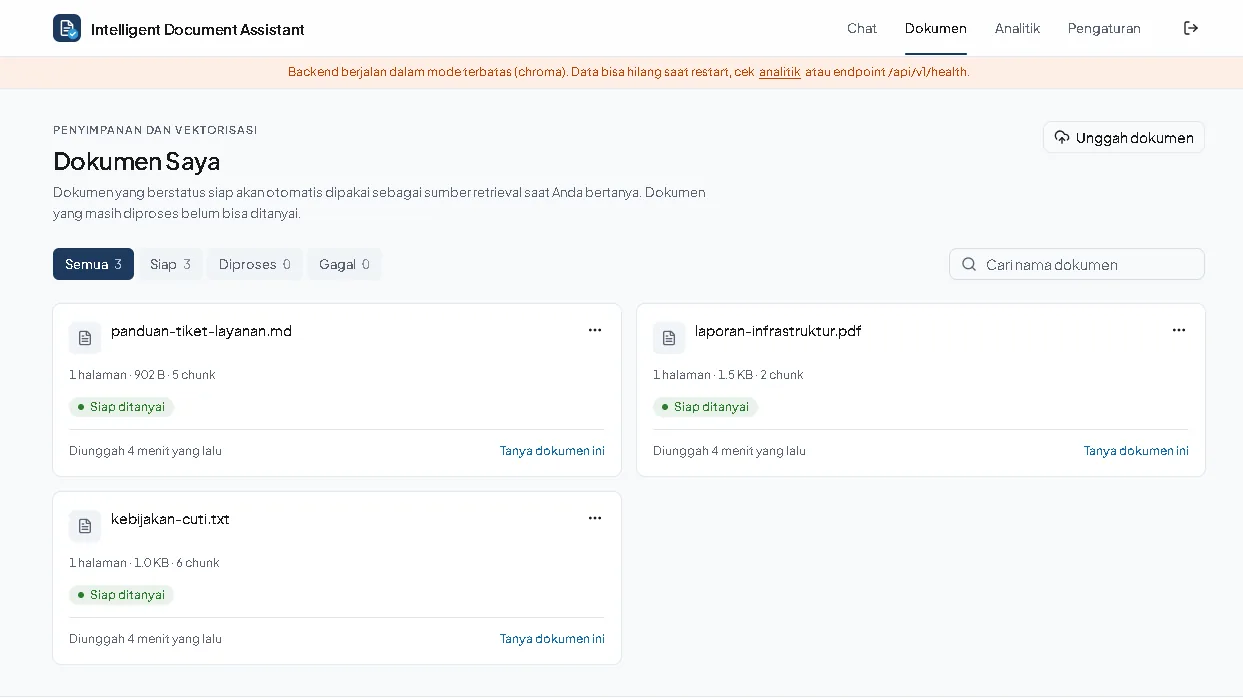
Documents
Upload PDF, TXT, or Markdown and follow indexing status until the file is ready to query.
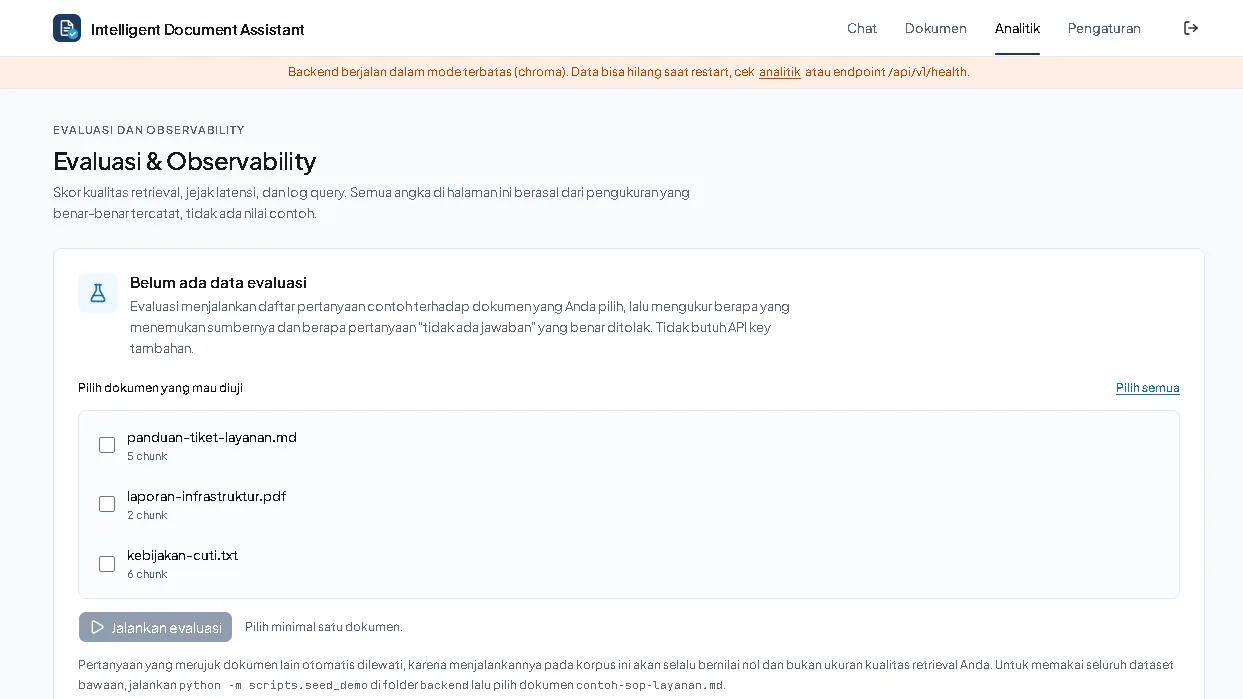
Analytics
Latency, source counts, and question logs, plus retrieval evaluation runs saved so changes can be compared.
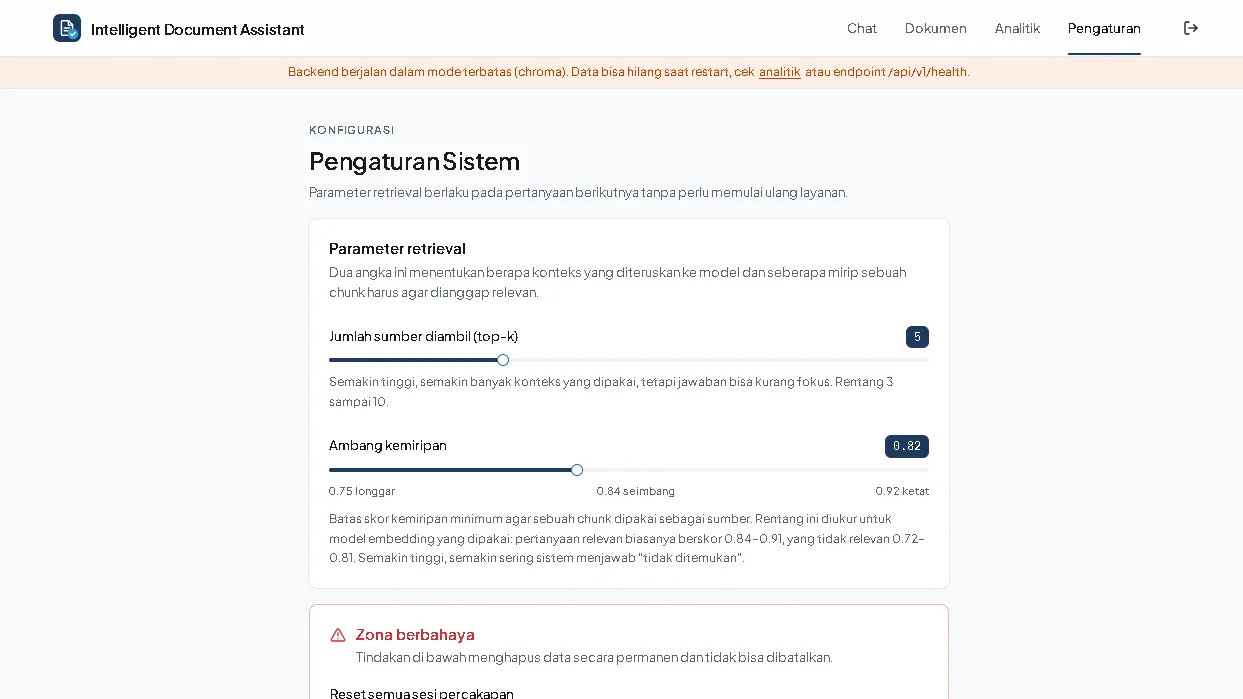
Settings
Top K and similarity threshold stored on the backend, so one retrieval behaviour applies to every session.
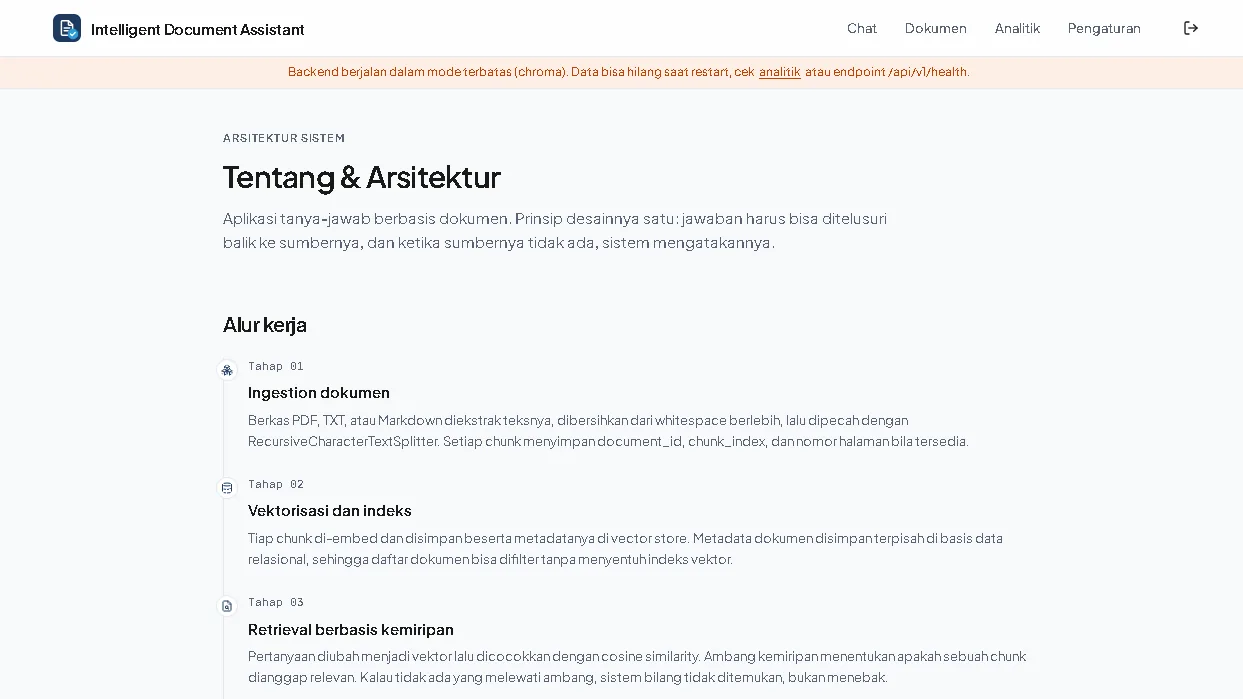
About and Architecture
The full path from upload to answer, with the stack and the reason behind each choice.