ML / Done
Smart Document Scanner & OCR Service
Overview
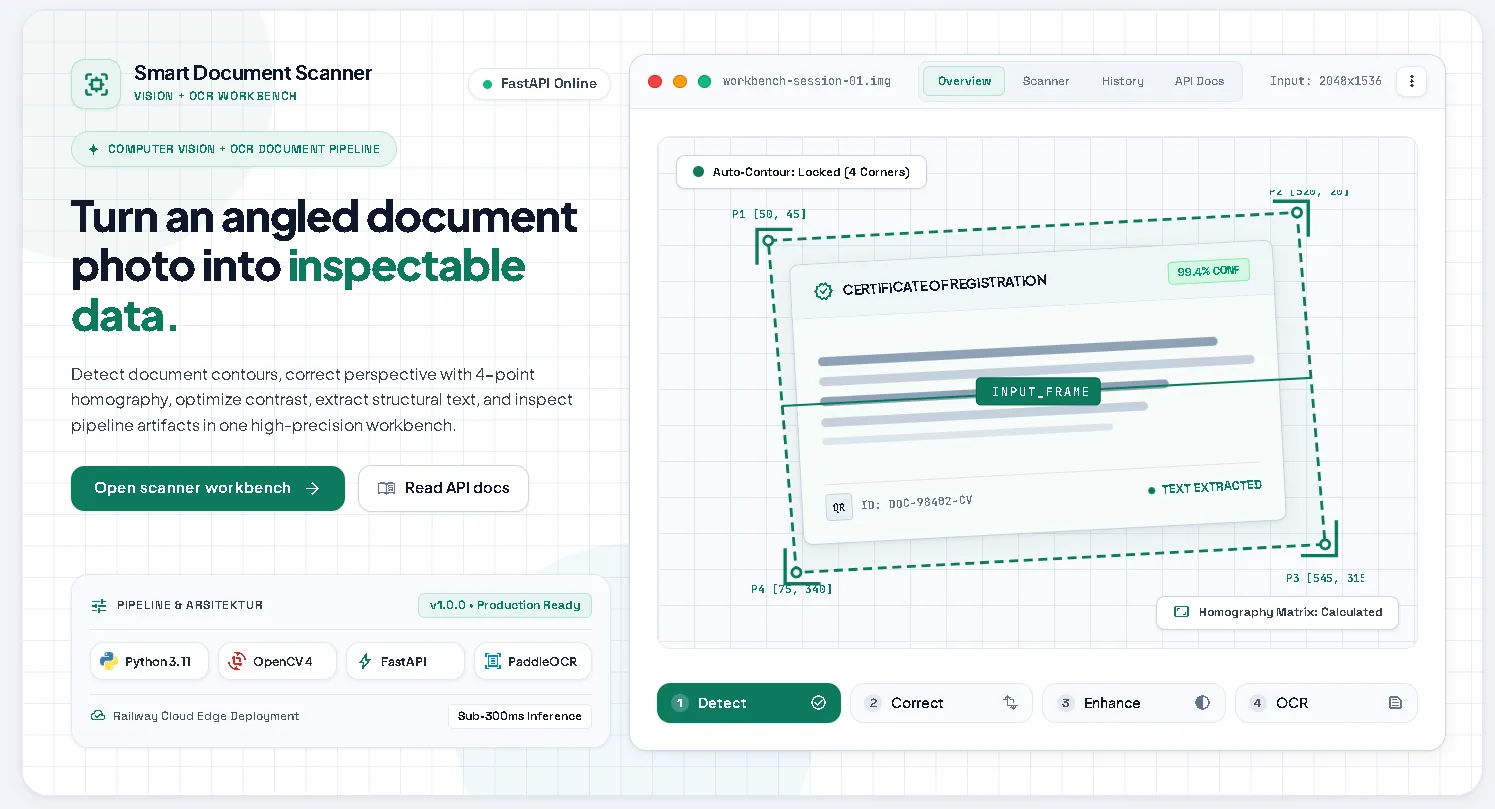
Production-ready scanning pipeline: detects a card or document in a photograph, corrects its perspective, enhances legibility, reads it with a neural OCR engine (RapidOCR / PP-OCRv6 on ONNX Runtime), and emits structured JSON where every field carries a confidence and the rule that produced it. The same Dockerfile runs locally, in Compose, and on Railway.
Challenge
Hard captures (cluttered desks, low light, blur, rotation, low contrast) pull in background text and drop characters, so the pipeline scores crops by recovered text coverage instead of confidence, keeps a full-frame fallback, and reports failures such as NO_DOCUMENT or NO_CONTENT rather than empty successes.
Result
Deployed from a three-stage Docker build with a C++17 accelerator, a batch CLI, and an anti-hardcoding CI gate. On the benchmark it scores 72.3% mean per-key with 67.2% exact matches and detection recall of 11 of 11 images, with every result traceable back to the pixels that produced it.
Key Statistics
72.3%
Mean per-key score
67.2% (43 of 64 keys)
Exact-match rate
11 / 11 images
Detection recall
~45 s per card on CPU
Recognition time
Technologies
Computer Vision
-
 Python
-
 OpenCV
-
 C++17
OCR
-
 RapidOCR (PP-OCRv6)
-
 ONNX Runtime
Backend
-
 FastAPI
- Uvicorn
Frontend
-
 Next.js
-
 React
Testing
- pytest
- Playwright
Deployment
-
 Docker
-
 Railway
Gallery
Scanning Pipeline
Detect, correct, enhance, read, parse: one photo to structured JSON.